Key takeaways
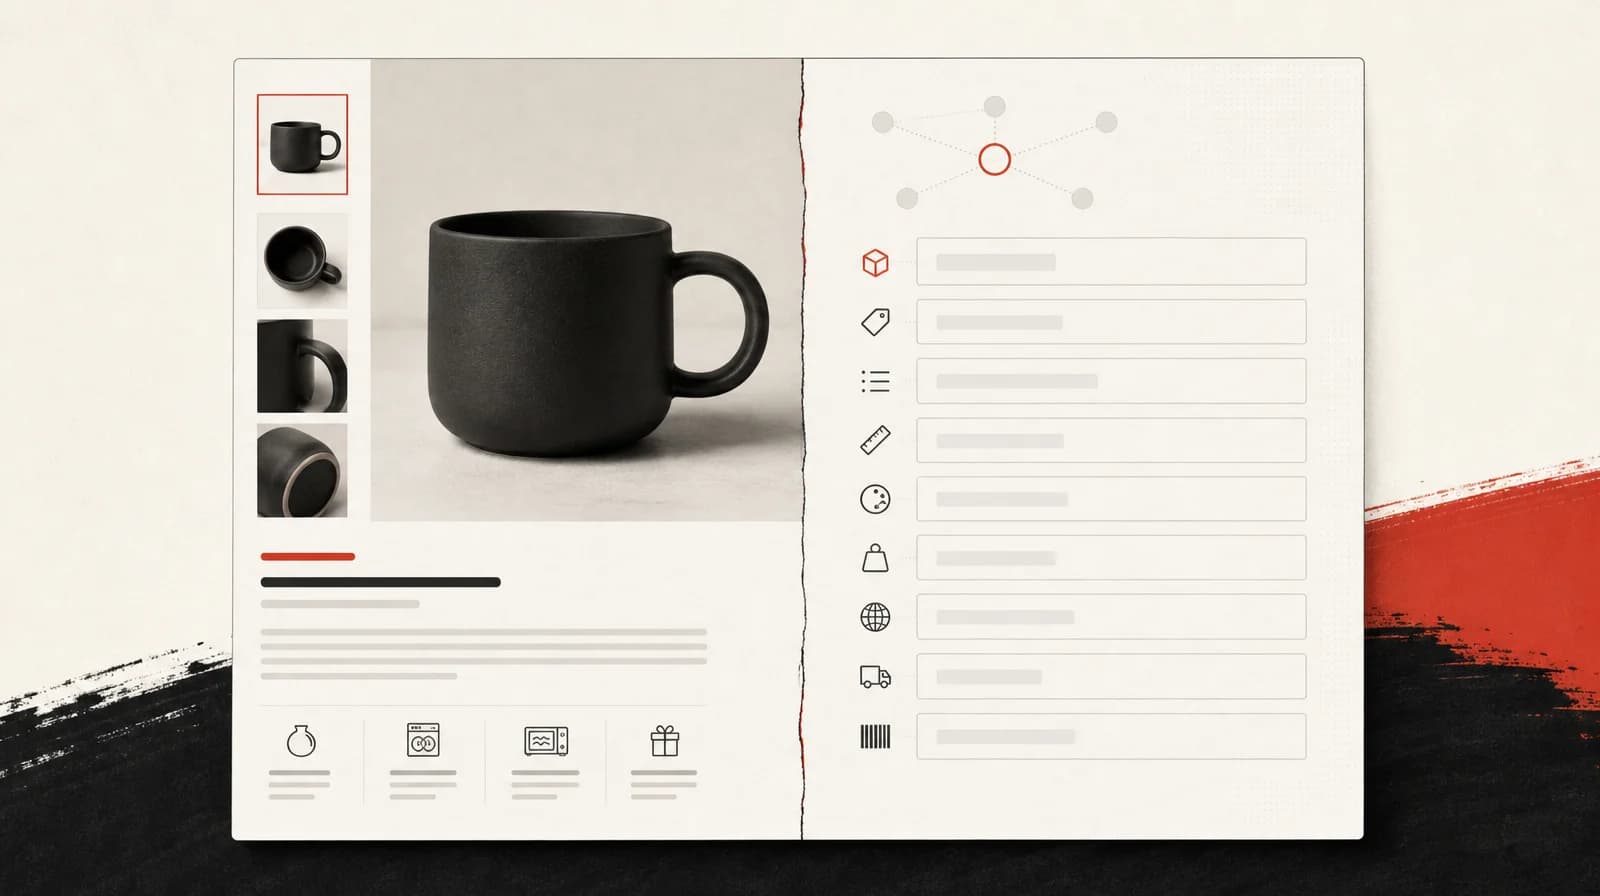
An AI agent can only recommend a product if its feed and product page expose structured identifiers, pricing, availability, media and delivery attributes in the format the protocol specifies; missing or stale fields, not model quality, are the usual reason recommendations fail.
Own reversible, read-only agent work end-to-end; gate anything irreversible, priced or customer-facing behind human
You are choosing between two decisions that get treated as one. The first is whether to build a proprietary shopping agent or integrate an existing one from OpenAI or Google. The second, upstream of it, is whether your product data can be read by any agent at all. Get the data decision wrong and the build-or-integrate conversation is academic: you will spend on a surface that cannot see the catalogue you need to sell.
The build-or-integrate decision is a data decision first
OpenAI's Agentic Commerce Protocol (ACP) publishes a required structure for the product data an agent will use to discover, price and recommend a SKU (S1). Google's Universal Commerce Protocol (UCP) uses the existing Merchant Center product feed as an entry point for AI Mode in Search and Gemini web (S6). ACP's structure is a published schema. OpenAI defines field names, data types, constraints and example values for discovery, pricing, availability and seller context, and merchants supply a structured feed file that OpenAI then ingests and indexes (S1). Non-Ads commerce feeds are governed separately from Ads feeds, so an existing Shopping ads export follows a different eligibility path (S1). The platform can only rank what it has been given in the format it accepts. The business still has to afford the stock, the margin and the fulfilment promise sitting underneath those fields.
ACP's merchant flow is four steps: format the catalogue to the spec, deliver it, wait for OpenAI to ingest, validate and index it for retrieval and ranking, then keep it fresh whenever products, prices or availability change (S2). The feed itself must carry identifiers, descriptions, pricing, inventory, media and fulfilment options, and it can be delivered as TSV, CSV, XML or JSON (S2). Community documentation of the same spec adds a validation sequence: send an initial sample feed for validation, then support updates as often as every 15 minutes and update inventory status promptly (S4, S5). ACP is positioned as an open standard co-developed by OpenAI and Stripe, and Instant Checkout in ChatGPT is still limited to approved partners even though building on the protocol is open to all (S3, S4). Openness of the spec and commercial access to checkout are two different gates. Record that distinction in the brief before anyone treats a complete feed as a checkout launch.
Google's route runs through the existing Merchant Center shopping feed you already maintain for Shopping ads, which is now also the entry point for AI Mode in Search and Gemini web (S6). The merchant remains merchant of record and keeps customer data and the relationship (S6). Native checkout is the default; an optional iframe-based embedded checkout exists only for specific approved merchants (S6).
Neither protocol requires you to build anything from scratch. Both require your existing product data to be complete and current in a format their systems can parse.
Build-versus-buy is the second question. A proprietary agent trained on an incomplete feed will invent stock levels and misprice variants as readily as a third-party one. The integration question only becomes worth answering once the data underneath is sound, because at that point the choice is about control: Google's UCP keeps you as merchant of record and lets you keep customer data and the relationship (S6). Discovery follows the same split: under UCP any vendor's agent can in principle discover a store by fetching a single URL with no per-platform registration; ACP discovery is currently limited to OpenAI's ecosystem (S16). That framing is useful for understanding the shape of each option. Treat any specific traffic-lift or cost-percentage number attached to it as unverified marketing, because no primary study in this evidence pack backs those figures.
What breaks when product data is incomplete
Adobe's AI Content Visibility Checker scores a page out of 100%. On that method, homepages scored 75%, category pages 74% and product pages 66%, with much SKU-level content currently invisible to LLMs (S10).
I haven't run Adobe's readability check specifically on a client's top PDPs. In practice I treat incomplete product_detail and feed attributes as a silent failure for anything that needs structured fields. I won't claim a measured lift from fixing those fields until we've logged pre/post on a real account. The operator move is fix the structured data first, then measure.
Digital Commerce 360's write-up of Adobe reported AI-referred retail traffic converting 54% better than non-AI traffic in May 2026, on more than a trillion visits to US retail sites, with that traffic up 138% year on year in the same month (S11). The panel is US retail, and the figure moves by month.
Google Merchant Center Help ties the product_detail attribute to discovery across AI-driven surfaces such as AI Mode in Google Search (S8). Google describes it as a way to supply technical specifications or other details not covered by other attributes, to give customers readable structured data, and to help customers discover product information across those AI-driven surfaces (S8). Each product_detail value must contain two colons separating three sub-attributes; malformed entries are unusable (S8). The owner of this work is whoever can edit the live feed and the two-colon product_detail format.
Freshness has its own threshold. ACP documentation states feeds can be updated as often as every 15 minutes, and inventory status should update promptly (S4, S5). If your feed sync runs nightly, an agent can recommend a product that sold out twelve hours ago. A stale feed can produce a cancelled order, a refund, and a customer who was told the pair was in stock. Google has also tightened the physical spec: S9 lists handling_cutoff_time, minimum_order_value, video_link, image_link and additional_image_link (S9). The 2026 specification update sets warnings from 14 April 2026 and enforcement from 31 January 2027 (S9). Those dates belong in a compliance calendar now.
SEO fixes and generic feed hygiene don't solve this
The instinct is to treat this as a content problem: rewrite product copy, add keywords, tidy the meta description. That helps classic search. It does little for agent readability, because the two systems are reading different things. Traditional SEO optimises rendered text for a crawler that indexes pages. Agent commerce protocols read structured fields: identifiers, descriptions, pricing, inventory, media and fulfilment options in a file the protocol can validate (S2). The protocol's own validation step checks the feed against its schema before anything goes live (S2).
I've seen the pattern: brief a copywriter to make descriptions "more AI-friendly" while size, material, GTIN, or other feed fields are still missing. You spot the wrong fix when human-readable copy improves but the agent still can't answer attribute questions that aren't in the structured data. The actual fix is feed completeness.
The other common failed approach is to ignore agent traffic on the grounds that it is still small. Elmo's synthesis of Contentsquare put AI-referred visits at around 0.2% of all visits even while reporting fast growth, which is why the wait argument still sounds reasonable in a weekly stand-up (S12). Waiting for volume before fixing readability means the feed work happens after growth has already started. The feed work is the same at 0.2% visit share as it is later, and it is cheaper to do while the queue is short. Dedicated tracking is a separate measurement question, covered in whether AI referral traffic is big enough yet to justify dedicated tracking.
Which workflows should the agent own, and which need a human signature?
Once the data question is answered, the workflow question is separate, and the evidence for it comes from agent governance practice generally, not from any ecommerce-specific study. Write the rule down so the team can apply it.
On our own stack the standing rule is read-only scopes by default. Anything that writes money (price, refund, spend) needs a human signature. The rule we use now is the agent can draft and flag, but price changes and refunds stay approval-gated until there's a locked playbook and an audit trail.
The published default splits work by reversibility and blast radius: read-only intelligence work (summarising, retrieving, classifying, drafting) can run autonomously; write actions and anything customer-facing should be supervised until the agent proves reliable (S13). The gating test is specific: require approval when the next action is irreversible, costly, regulated, or has a wide blast radius if wrong (S13). The rollout sequence that follows is to propose first, then execute after review. Architecturally, that means a hard split between propose and execute: propose is presenting a structured action payload to a reviewer before execution (S13). Delay in that queue usually comes from poor routing and incomplete context rather than from the human step itself. The goal is supervised autonomy: a reviewer who can see a complete payload and a recorded decision (S13).
This is generic agent-oversight writing. No source found assigns these modes to a D2C catalogue, a refund queue or a paid-media account, so the mapping below is reasoned application of that rule.
Mapped onto ecommerce work, that reads roughly like this:
- Autonomous, end to end: feed formatting and validation against the protocol spec, attribute enrichment from existing catalogue data, stock-status syncing, flagging pages that fail a readability check.
- Propose, then a human approves: price changes outside a pre-agreed band, promotional copy going live, new product launches into the agent-facing feed, anything touching a customer refund or a return exception.
- Never autonomous without a separate policy review: budget reallocation across paid channels, discount depth beyond a set floor, customer communications that reference a specific order.
That mapping applies the general rule to named jobs; it is not lifted from an ecommerce-specific study. Ownership should be explicit: catalogue owns feed formatting and stock sync; merchandising owns price-band exceptions; finance or CX owns refunds; media owns any budget move. Stop the autonomy expansion if a write action is irreversible, customer-facing, or spends money the agent has not been given a margin for.
The unresolved part is real. Across the sources in this brief, platforms assert that structured attributes feed AI discovery, and none of them includes a controlled before/after on what happens to recommendation eligibility when a specific attribute is missing. Treat this framework as a starting position to test.
A related discipline: once an agent recommendation layer is doing the relevance work, the manual merchandising rules built for search-era catalogues stop earning their keep. We cover the SKU side of that in do you retire product rules, or judge SKUs on CM2?
The attribute baseline and reviewer requirements
The autonomy mapping is set out in the preceding workflow section; this beat focuses on product-data requirements and reviewer workload.
Pulling the required-field picture together: an agent needs, at minimum, stable identifiers, accurate pricing and availability, delivery information, media, fulfilment options, and populated technical-detail fields in the exact structured format each protocol specifies, refreshed on a cadence the protocol also specifies (S1, S2, S3, S6, S8). ACP's 15-minute figure is a freshness ceiling. It does not mean hourly syncing is fine if stock turns over faster than that (S4, S5). On Google, native checkout is the default path through Merchant Center; iframe checkout is an exception for approved merchants, and should not be the plan you assume (S6).
The specific field-by-field reference lives on the live protocol documentation, because both ACP and UCP are still moving specs; read the source directly before you build a feed against it rather than trusting a summary that ages. Third-party claims that a particular attribute-count threshold multiplies visibility are unsupported in the evidence pack, so they are not a planning number. Leave an unsupported multiplier out of a board slide.
The reviewer-fatigue risk on the workflow side is worth naming plainly. Pickaxe's guide on human-in-the-loop agents says the failure that gets people is a reviewer clicking approve without looking at the payload (S14). If you build an approval queue, size it to what someone will actually read, and keep the payload complete enough that the reviewer is not guessing.
What the readability and conversion data actually show
The Adobe figure to take into a budget meeting is May 2026, as reported by Digital Commerce 360: AI-referred retail traffic up 138% year on year, converting 54% better than non-AI traffic, measured on more than a trillion visits to US retail sites (S11). Date-stamp the window when using the figure.
Elmo's synthesis is the scale check that an Adobe-only reading lacks. Adobe measured a relative premium (54% better). Contentsquare's 99-billion-session benchmark put AI-referred conversion at 1.3% in 2025, still below email at 1.9%, with AI-referred visits around 0.2% of all visits (S12). Elmo notes the two conversion figures are not directly comparable: one is a relative premium, the other is an absolute rate (S12). The 0.2% visit share is why the wait argument still appears in stand-ups. The relative premium is why unreadability now has a revenue cost on the visits that do arrive.
The agent cart-abandonment number in circulation is weaker. Presenc.ai published a modelled estimate of 78.6% agent cart abandonment against a roughly 70% human benchmark, and attributed 26% of that agent abandonment to stale price or stock data (S17). The source describes this as modelled from observed agent sessions and vendor benchmarks, with no disclosed panel size (S17). It is a modelled estimate with no disclosed panel size. It has not been observed at scale. The public baseline for agent abandonment by product category does not exist in this evidence pack. If the business needs one, it has to instrument its own checkout.
All of the conversion and readability telemetry above is US retail and largely one vendor's measurement. That does not settle how a UK D2C catalogue will behave.
Start with an audit, not a rebuild
Audit the highest-revenue product pages against the readability and freshness checks before anyone touches protocol integration or agent build decisions. Confirm the required structured attributes are populated and correctly formatted (S8). Check your feed sync cadence against the 15-minute ACP benchmark, and if you have not sent a sample feed for validation yet, that is the first ACP step, ahead of any storefront rebuild (S4, S5). Put handling_cutoff_time, minimum_order_value, video_link, image_link and additional_image_link on the same checklist (S9). Warnings begin 14 April 2026 and enforcement begins 31 January 2027 (S9). Confirm you have an active Merchant Center account and eligible products before treating UCP as a live distribution path (S7).
Only once those pass should the build-versus-integrate conversation start. At that point the remaining choice is which distribution surface to use. Who owns the next step: the person who can export the current product feed and the highest-revenue product URLs this week. Stop if those pages already parse cleanly, the feed is within the freshness window, and the 2026/2027 Google attributes are populated. If those checks fail, stay on the audit. Protocol integration waits until they pass.
Sources
- OpenAI Developers — Product Feed Spec (Agentic Commerce) developers.openai.com OpenAI publishes a formal product schema for agent commerce defining field names, data types, constraints and example values for discovery, pricing, availability and seller context.
- Agentic Commerce Protocol docs — Product Feed Spec agentic-commerce-protocol.com Four-step merchant flow: format catalogue to spec, deliver it, OpenAI ingests/validates/indexes for retrieval and ranking, then keep it fresh on product, price or availability changes.
- Agentic Commerce Protocol docs — Key Concepts agentic-commerce-protocol.com Instant Checkout in ChatGPT is limited to approved partners even though building on ACP is open to all.
- Agentic Commerce Protocol — Product Feed Specification (community docs) agenticcommerce.expert Update frequency can be as often as every 15 minutes.
- Agentic Commerce Protocol — Key Concepts (community mirror) agenticcommerce.pro Send an initial sample feed for validation; support updates as often as every 15 minutes; update inventory status promptly.
- Google Developers — Getting started with Universal Commerce Protocol on Google developers.google.com Merchant remains Merchant of Record and keeps customer data and relationships.
- Google Developers Blog — Under the Hood: Universal Commerce Protocol developers.googleblog.com UCP is described as vendor-agnostic and open-source, compatible with Agent Payments Protocol (AP2).
- Google Merchant Center Help — Product detail [product_detail] support.google.com The product_detail attribute is explicitly tied by Google to discovery across AI-driven surfaces such as AI Mode in Google Search.
- Google Merchant Center Help — Product data specification update 2026 support.google.com New attributes: handling_cutoff_time and minimum_order_value; new optional video_link; minimum image resolution raised to 500x500 pixels.
- Adobe Business Blog — AI traffic grows but retail sites lag in AI search visibility business.adobe.com AI Content Visibility Checker scores: homepages 75%, category pages 74%, product pages 66%.
- Digital Commerce 360 — Adobe: AI-referred traffic to retail sites doubles in a year digitalcommerce360.com AI-referred retail traffic up 138% year on year in May 2026, converting 54% better than non-AI traffic, based on over a trillion visits to US retail sites.
- Elmo — AI Referral Traffic Conversion Rates: 2026 Data elmohq.com Reconciles Adobe's 54% relative premium against Contentsquare's absolute 1.3% AI-referred conversion rate (versus email's 1.9%) on a 99-billion-session benchmark, noting the two figures are not directly comparable.
- StackAI — Human-in-the-Loop AI Agents: How to Design Approval Workflows stackai.com Read-only work can be autonomous by default; write actions and external communications should be supervised until proven safe.
- Pickaxe — Human-in-the-Loop AI Agents pickaxe.co Different modes can coexist inside one agent: autonomous reads, monitored outreach, approval-gated refunds.
- Galileo — Human-in-the-Loop Agent Oversight galileo.ai Multi-tier oversight model: operators approve high-level plans, lower-level agents execute with bounded autonomy and escalation triggers.
- DEV Community — UCP vs ACP in 2026: A Technical Comparison dev.to Architectural contrast: ACP hub-and-spoke (merchant submits feed to OpenAI) versus merchant-hosted UCP (merchant runs endpoints, signing keys, uptime).
- Presenc.ai — Agent Cart Abandonment Statistics 2026 presenc.ai Vendor-modelled estimate of 78.6% agent cart abandonment versus a roughly 70% human benchmark, with stale price or stock data attributed to 26% of agent abandonment; source itself describes this as modelled, not observed at scale, with no disclosed panel size.